Ground AI and agents in enterprise data
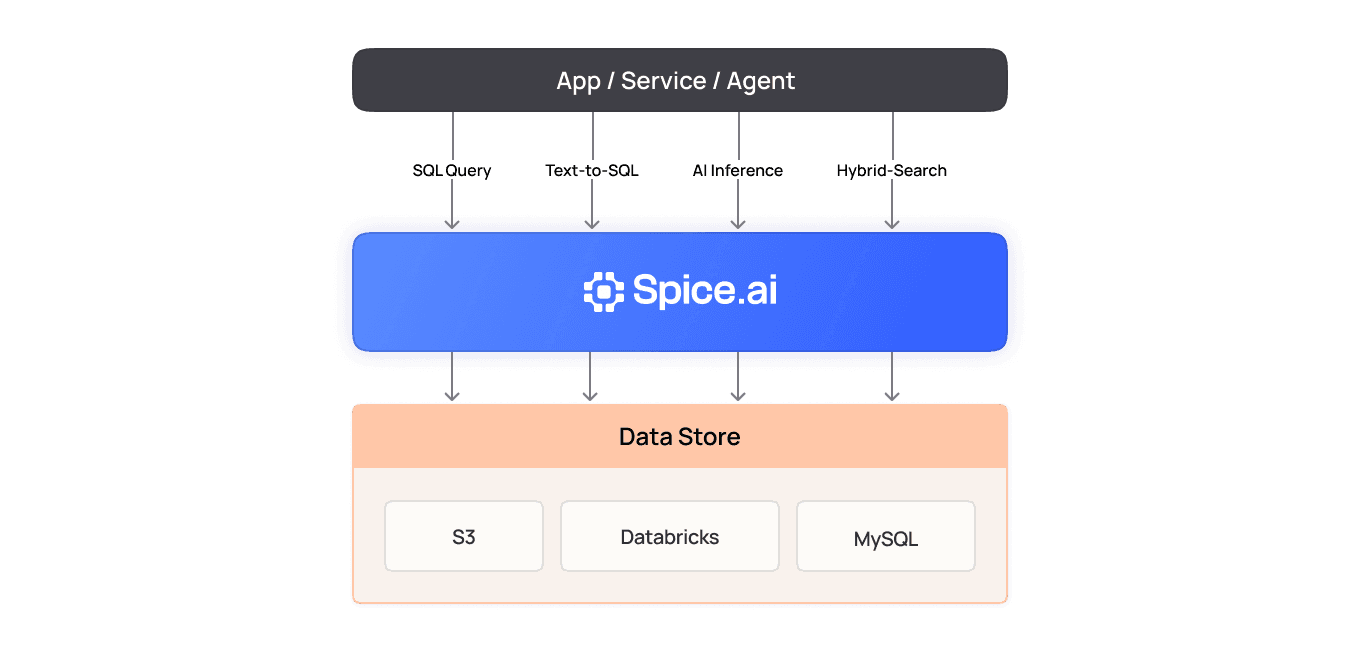
Build RAG pipelines, agent tools, and application search on one retrieval layer. Combine vector, full-text, and keyword search with SQL over live, structured, and unstructured data.
Do more with your data
100x
up to 100x faster queries
80%
up to 80% cost savings on data lakehouse spend
2x
Increase in data reliability
RAG breaks down without unified, real-time data
Good retrieval blends keyword search for precision, full-text search for context, and vector search for meaning. Fragmented RAG pipelines split these methods across separate search engines, connectors, and model APIs. Models and agents then answer from incomplete or outdated data, which leads to hallucinations, inconsistent results, and production risk.
Build data-grounded AI faster
Deliver accurate, context-rich results by combining SQL federation, hybrid search, and LLM inference in one governed runtime.
Federate structured data
Query operational and analytical data across databases, object stores, and APIs using standard SQL. All in real time with zero ETL.
Learn more about Spice federation
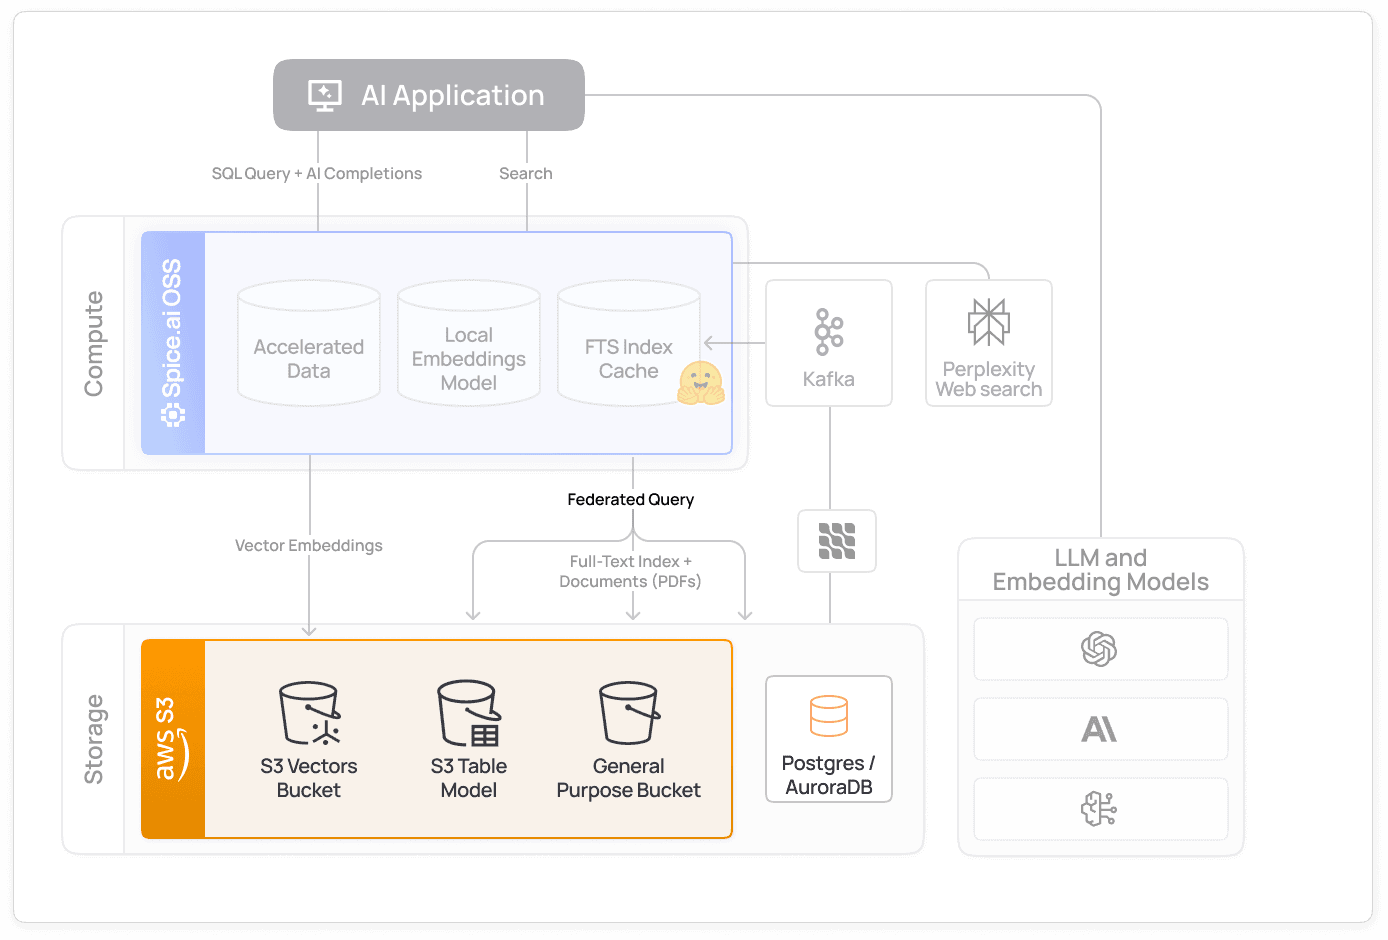
Search and embed unstructured data
Create embeddings from text, documents, or logs using local or hosted models. Run vector similarity search directly inside Spice to find relevant context, semantic matches, and related insights instantly.
Learn how hybrid search works
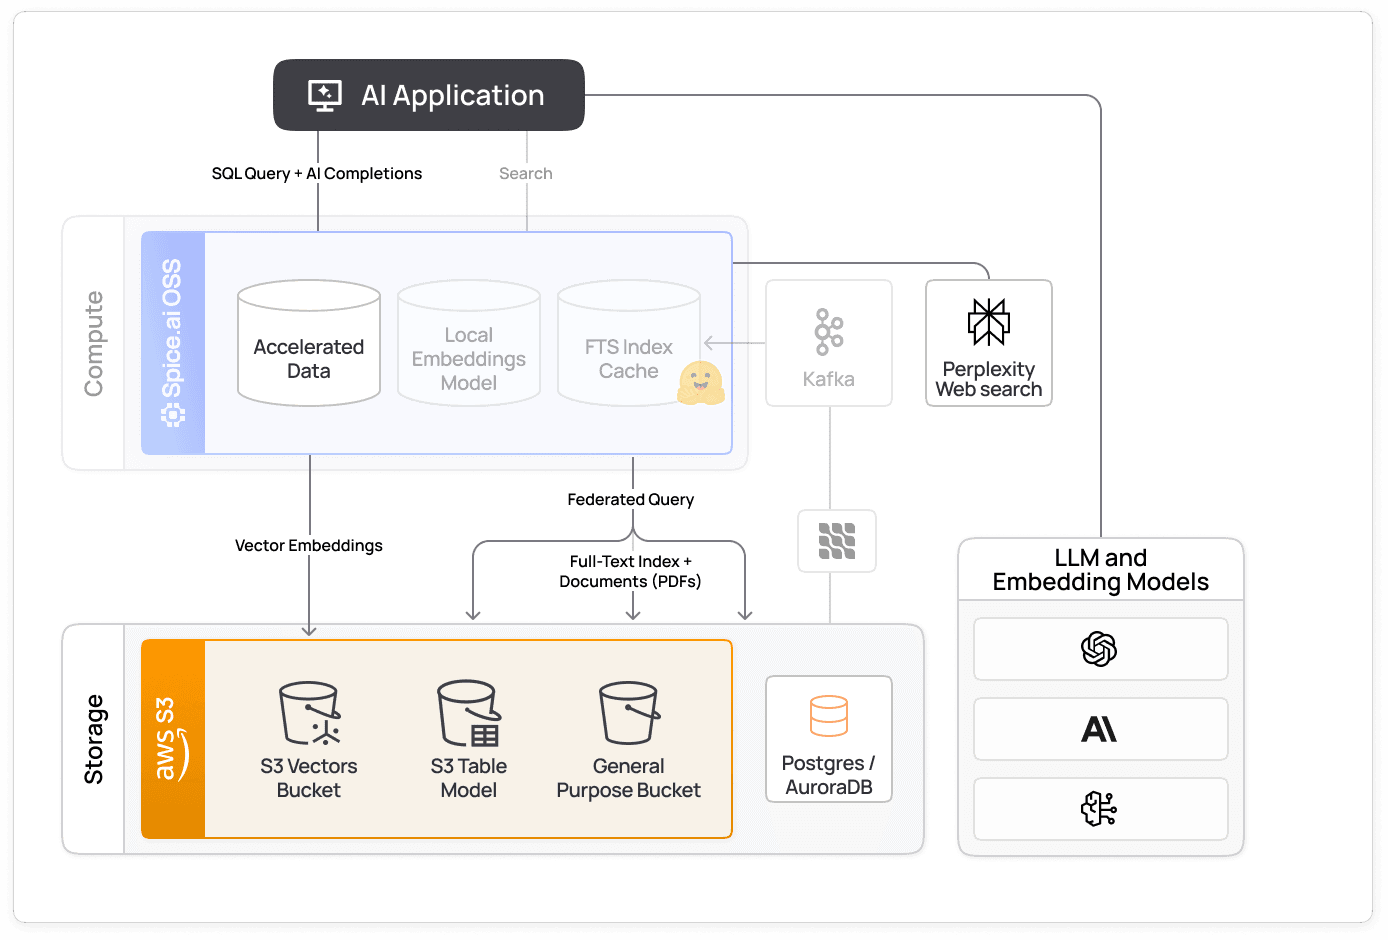
Retrieve and augment intelligently
Blend structured SQL results and semantic search results in one query using hybrid search. Deliver precise, context-rich data to your LLMs without manual data engineering or pipeline maintenance.
Learn about real-time hybrid search using RRF
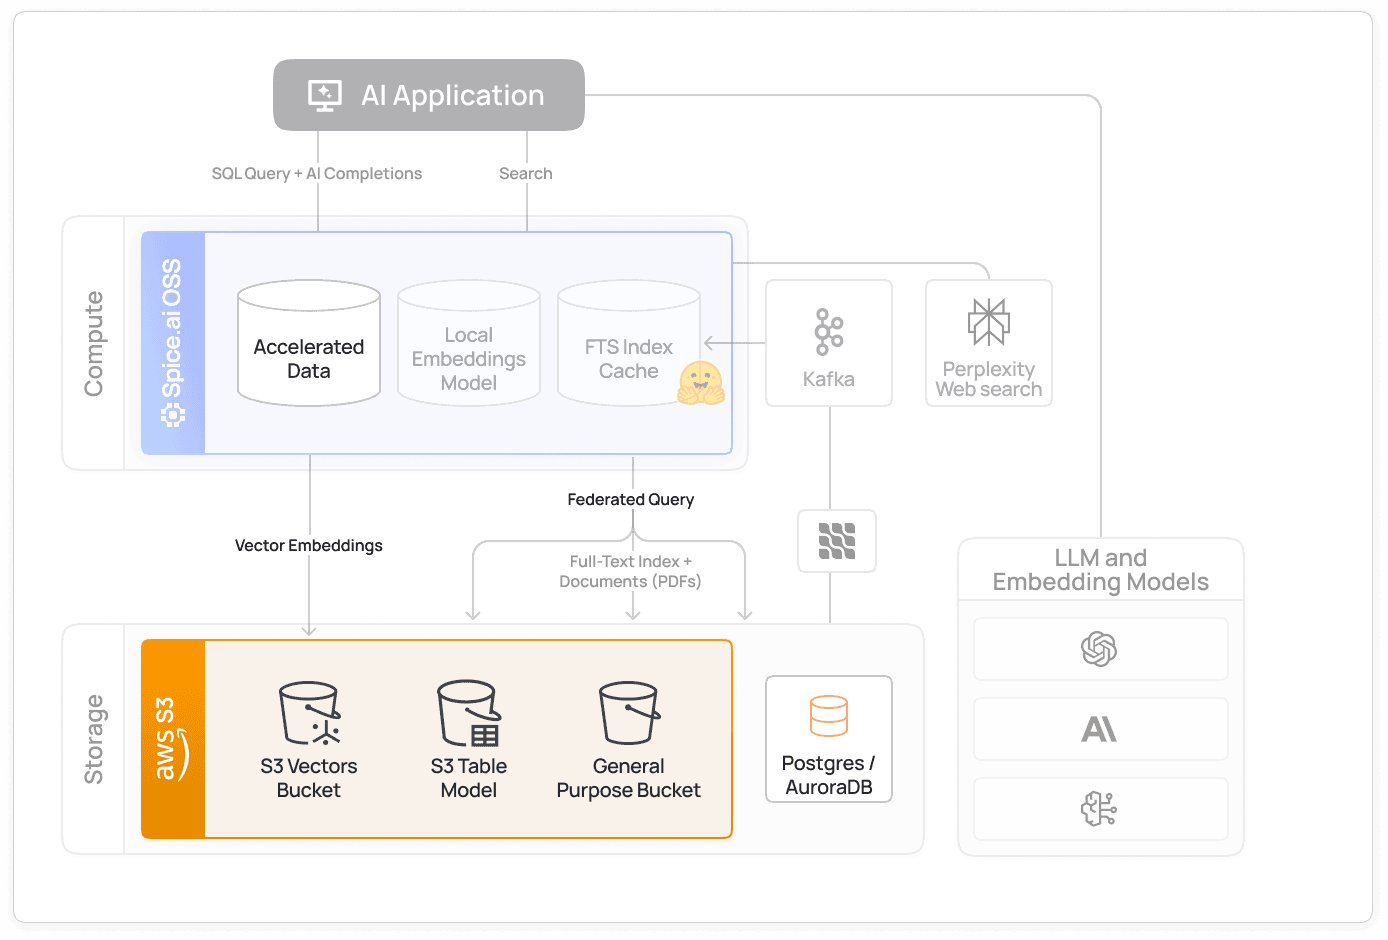
Generate insights with the AI Gateway
Invoke and run models like OpenAI, Anthropic, or local LLMs directly in SQL queries. Feed retrieved context into the model and generate accurate, compliant, and contextual results within the same SQL workflow.
Explore LLM inference and AI model serving
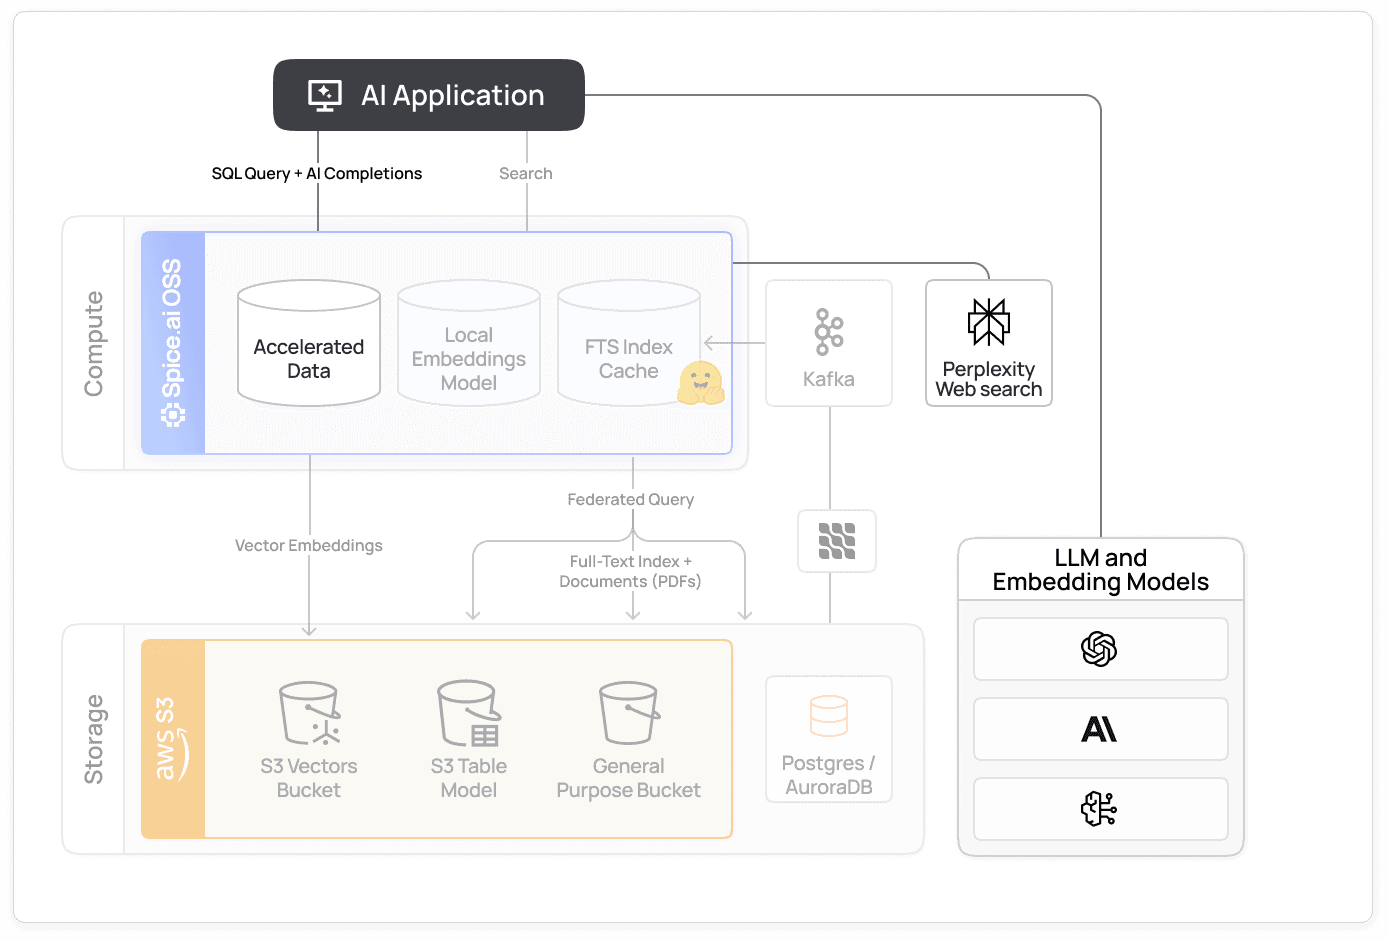
Hybrid search in one SQL query
Run vector, full-text, and keyword search in standard SQL, next to your filters and joins. Scale to billions of embeddings without a separate search engine or ETL pipeline.
Compose hybrid search in SQL
Call vector_search and text_search in one query, and fuse the results with rrf(). Results are tables, so you can filter, join, and aggregate them with the rest of your data.
Explore search features
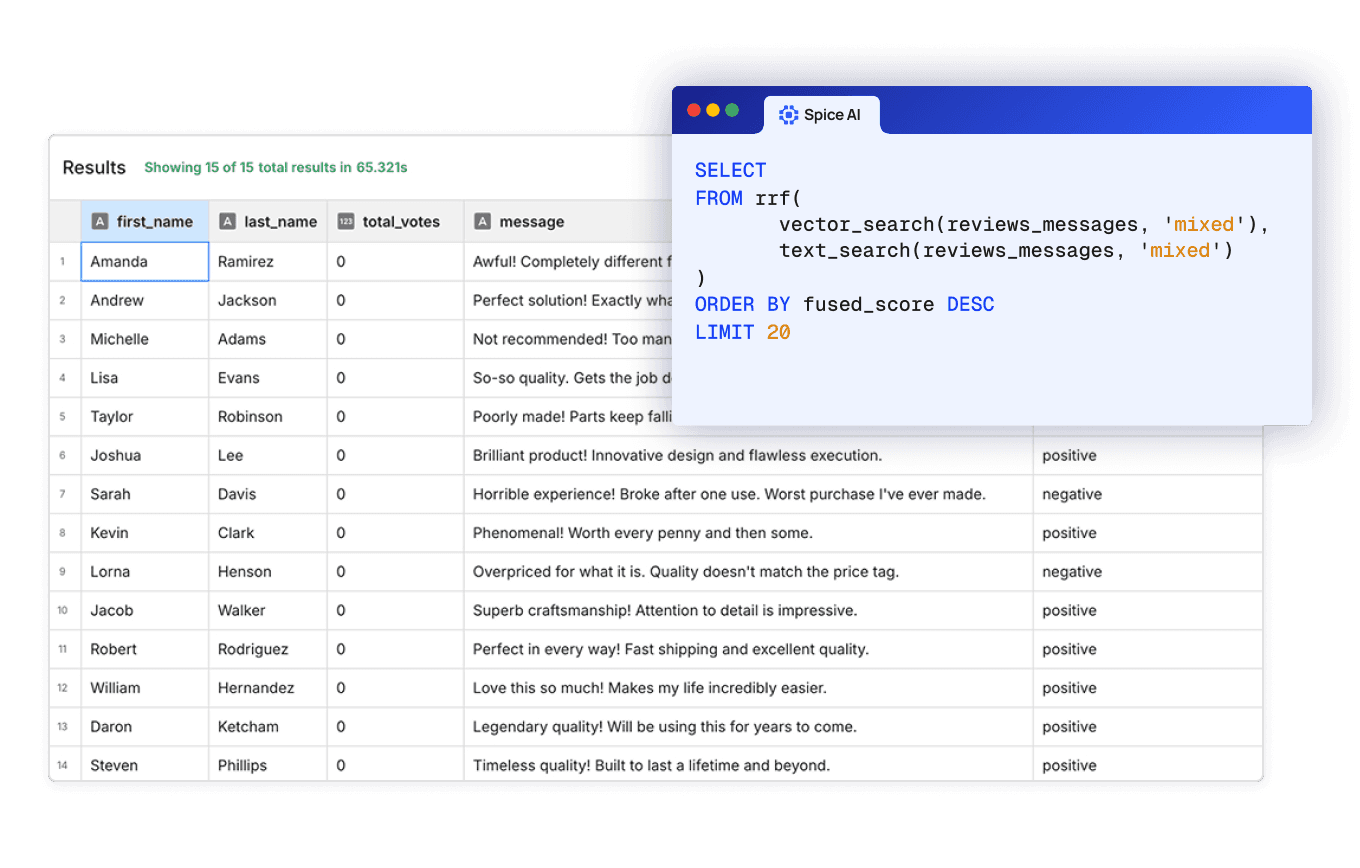
Tune relevance per query
Set a rank_weight on each search, and add a recency decay on a time column to rank newer rows higher. Reciprocal Rank Fusion merges ranks, so scores on different scales need no normalization.
Explore Reciprocal Rank Fusion
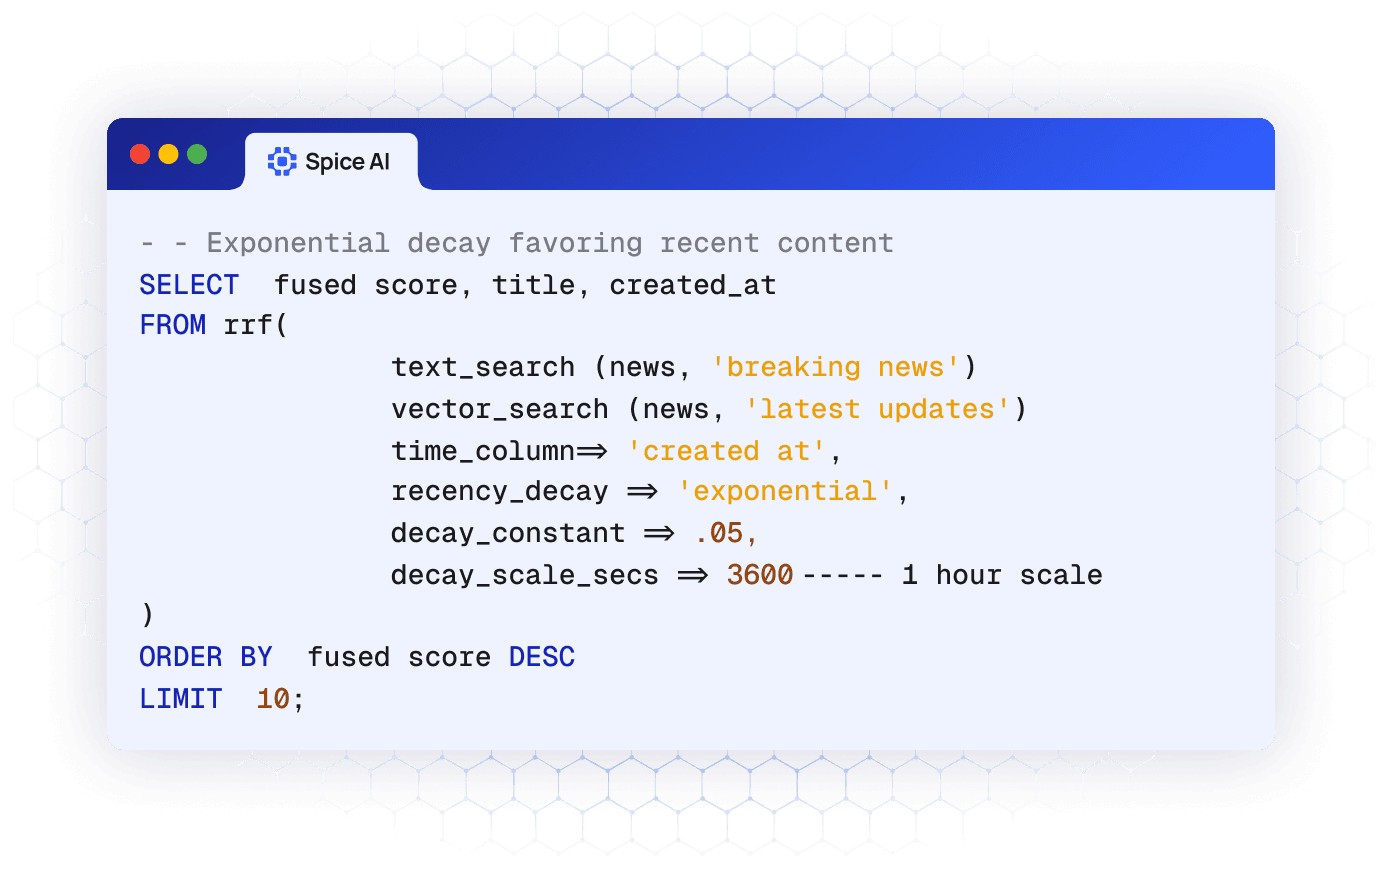
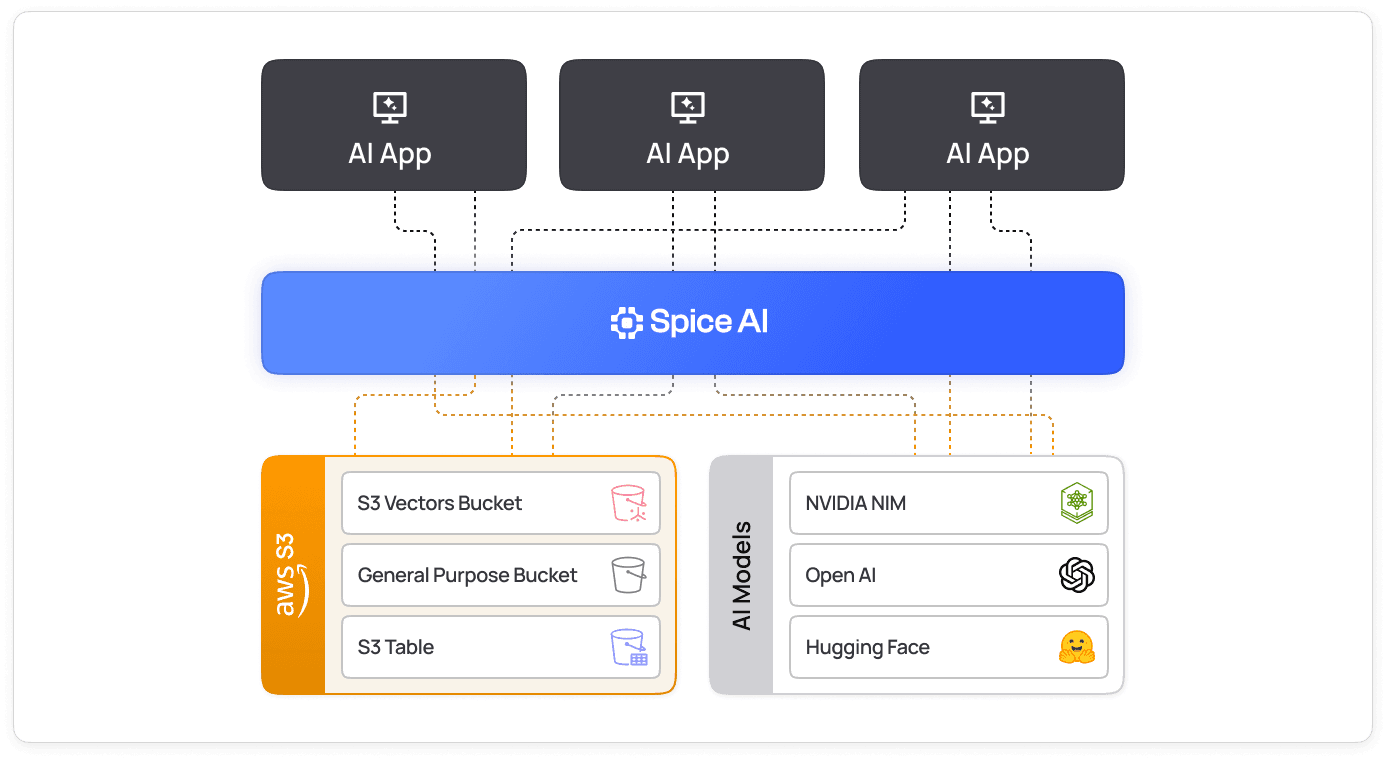
Search billions of vectors in Amazon S3
Store, index, and retrieve embeddings with partitioned Amazon S3 Vectors indexes. Spice manages ingest, refresh, and metadata for each index, and embeds with hosted or local models.
See S3 Vectors docs
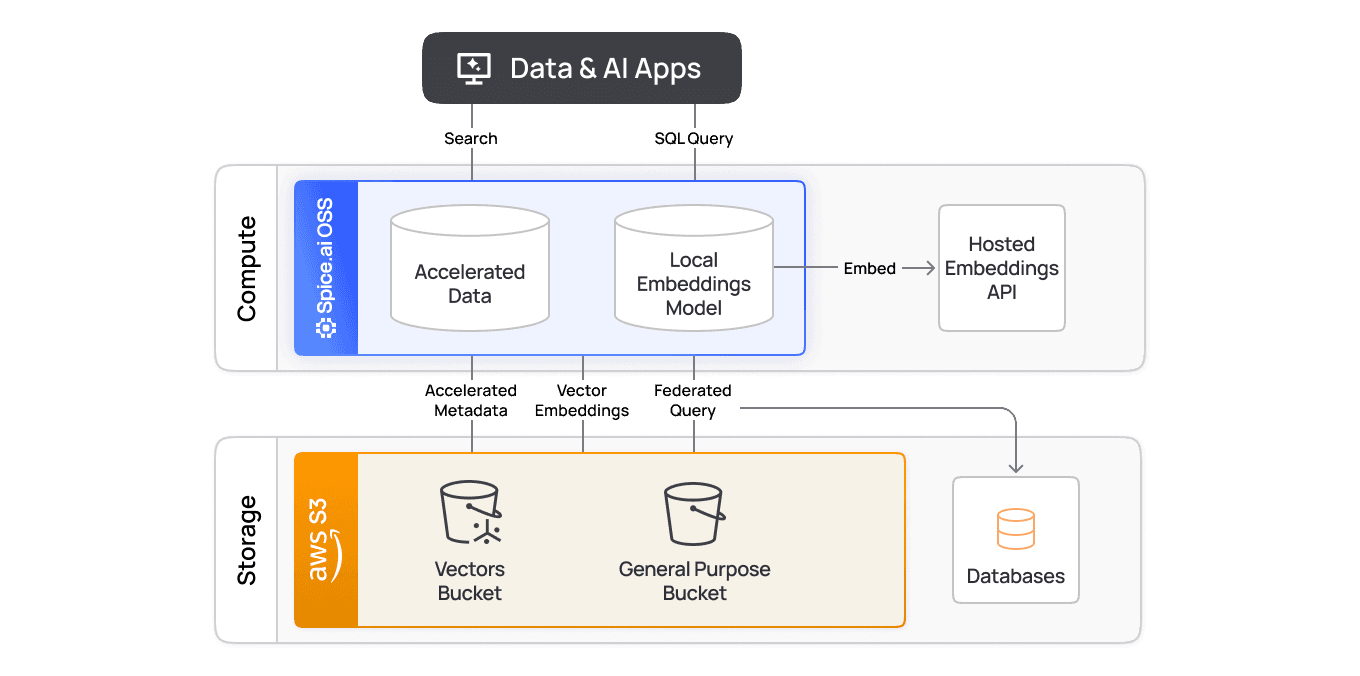
Serve hot data locally
Materialize hot data with DuckDB, SQLite, or Spice Cayenne acceleration, and keep large vector indexes in object storage. Index-only reads and filter pushdown keep common queries predictable.
Explore Spice Cayenne
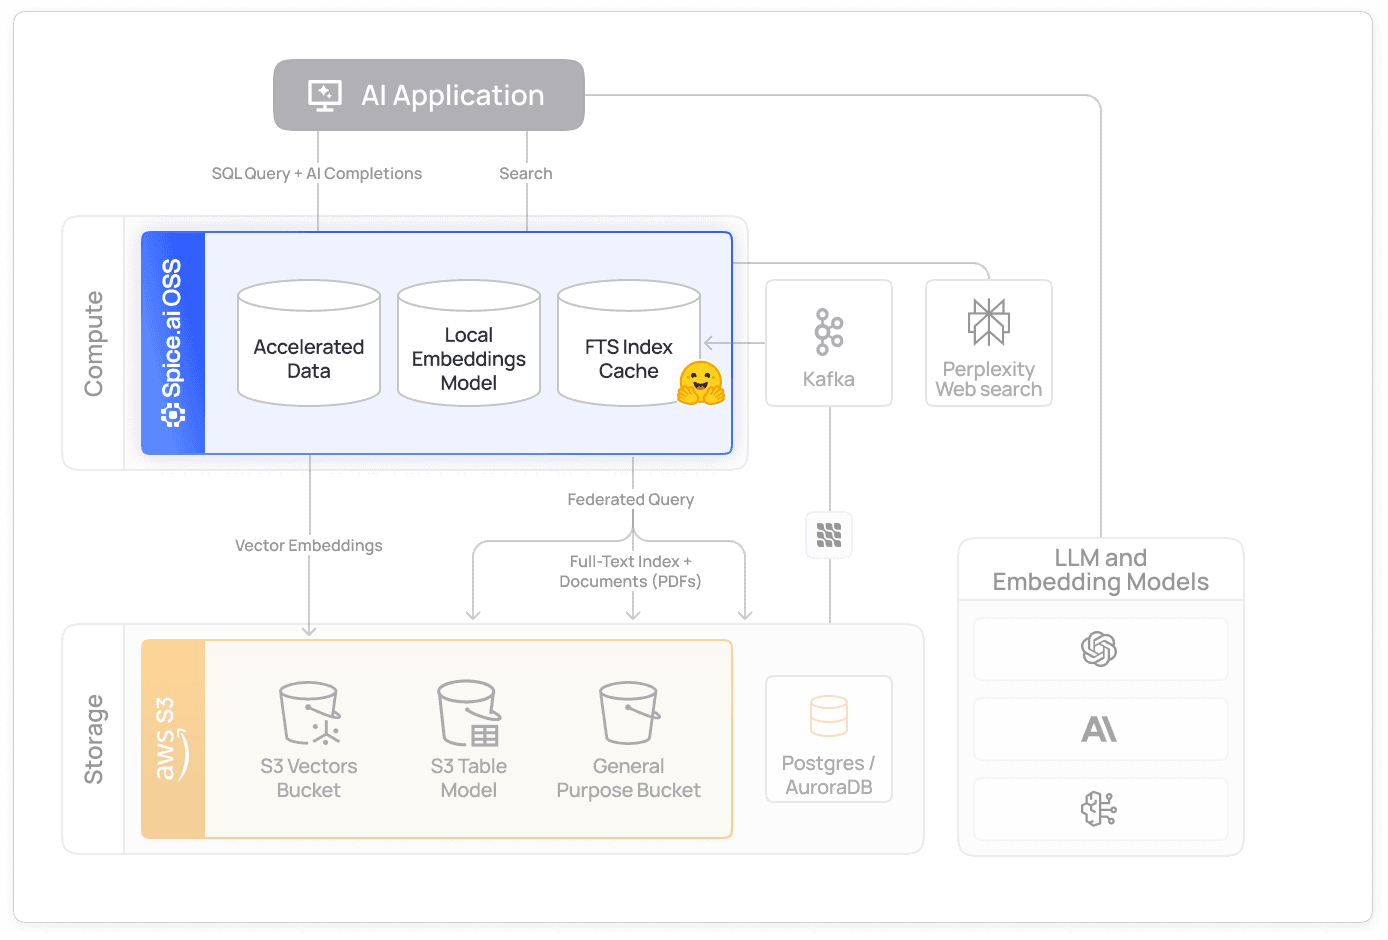
Give agents retrieval as a tool
Agents call the built-in search and SQL tools over the Model Context Protocol (MCP), or through a model that Spice serves. Each tool call runs hybrid search or SQL in the same runtime, over only the datasets in the Spicepod.
Why choose Spice for RAG and agentic retrieval
Spice unifies data retrieval, hybrid search, and AI generation in one runtime. There are no pipelines to orchestrate and no copies to drift.

Real-Time Federation
Query all your sources with federated SQL. No data movement or batch syncs.

Built-in Hybrid Search
Run vector, full-text, and keyword search next to SQL filters and joins.

SQL LLM Inference
Call, prompt, and evaluate models in SQL via the AI() SQL function

Hybrid Ranking
Blend multiple result sets with Reciprocal Rank Fusion for per-query weighting and tunable relevance.

Governed & Secure
Enterprise-grade access control ensures compliance and auditability.

Deployment Flexibility
Run Spice anywhere: as a sidecar, microservice, cluster, or on the managed Spice Cloud Platform.
Trusted by teams building intelligent applications
Run data-intensive workloads on a high-performance engine trusted by teams building real-time systems at scale.
“Partnering with Spice AI has transformed how NRC Health delivers AI-driven insights. By unifying siloed data across systems, we accelerated AI feature development, reducing time-to-market from months to weeks - and sometimes days. With predictable costs and faster innovation, Spice isn't just solving some of our data and AI challenges - it's helping us redefine personalized healthcare.”
Tim Ottersburg
VP of Technology, NRC Health
“Spice AI grounds AI in our actual data, using SQL queries across many data sources. This brings accuracy to probabilistic AI systems, which are very prone to hallucinations.”
Rachel Wong
CTO, Basis Set
Trusted by global enterprises
Build a scalable RAG app
Guides and examples to learn more about building RAG applications with Spice.
Hybrid Search Docs
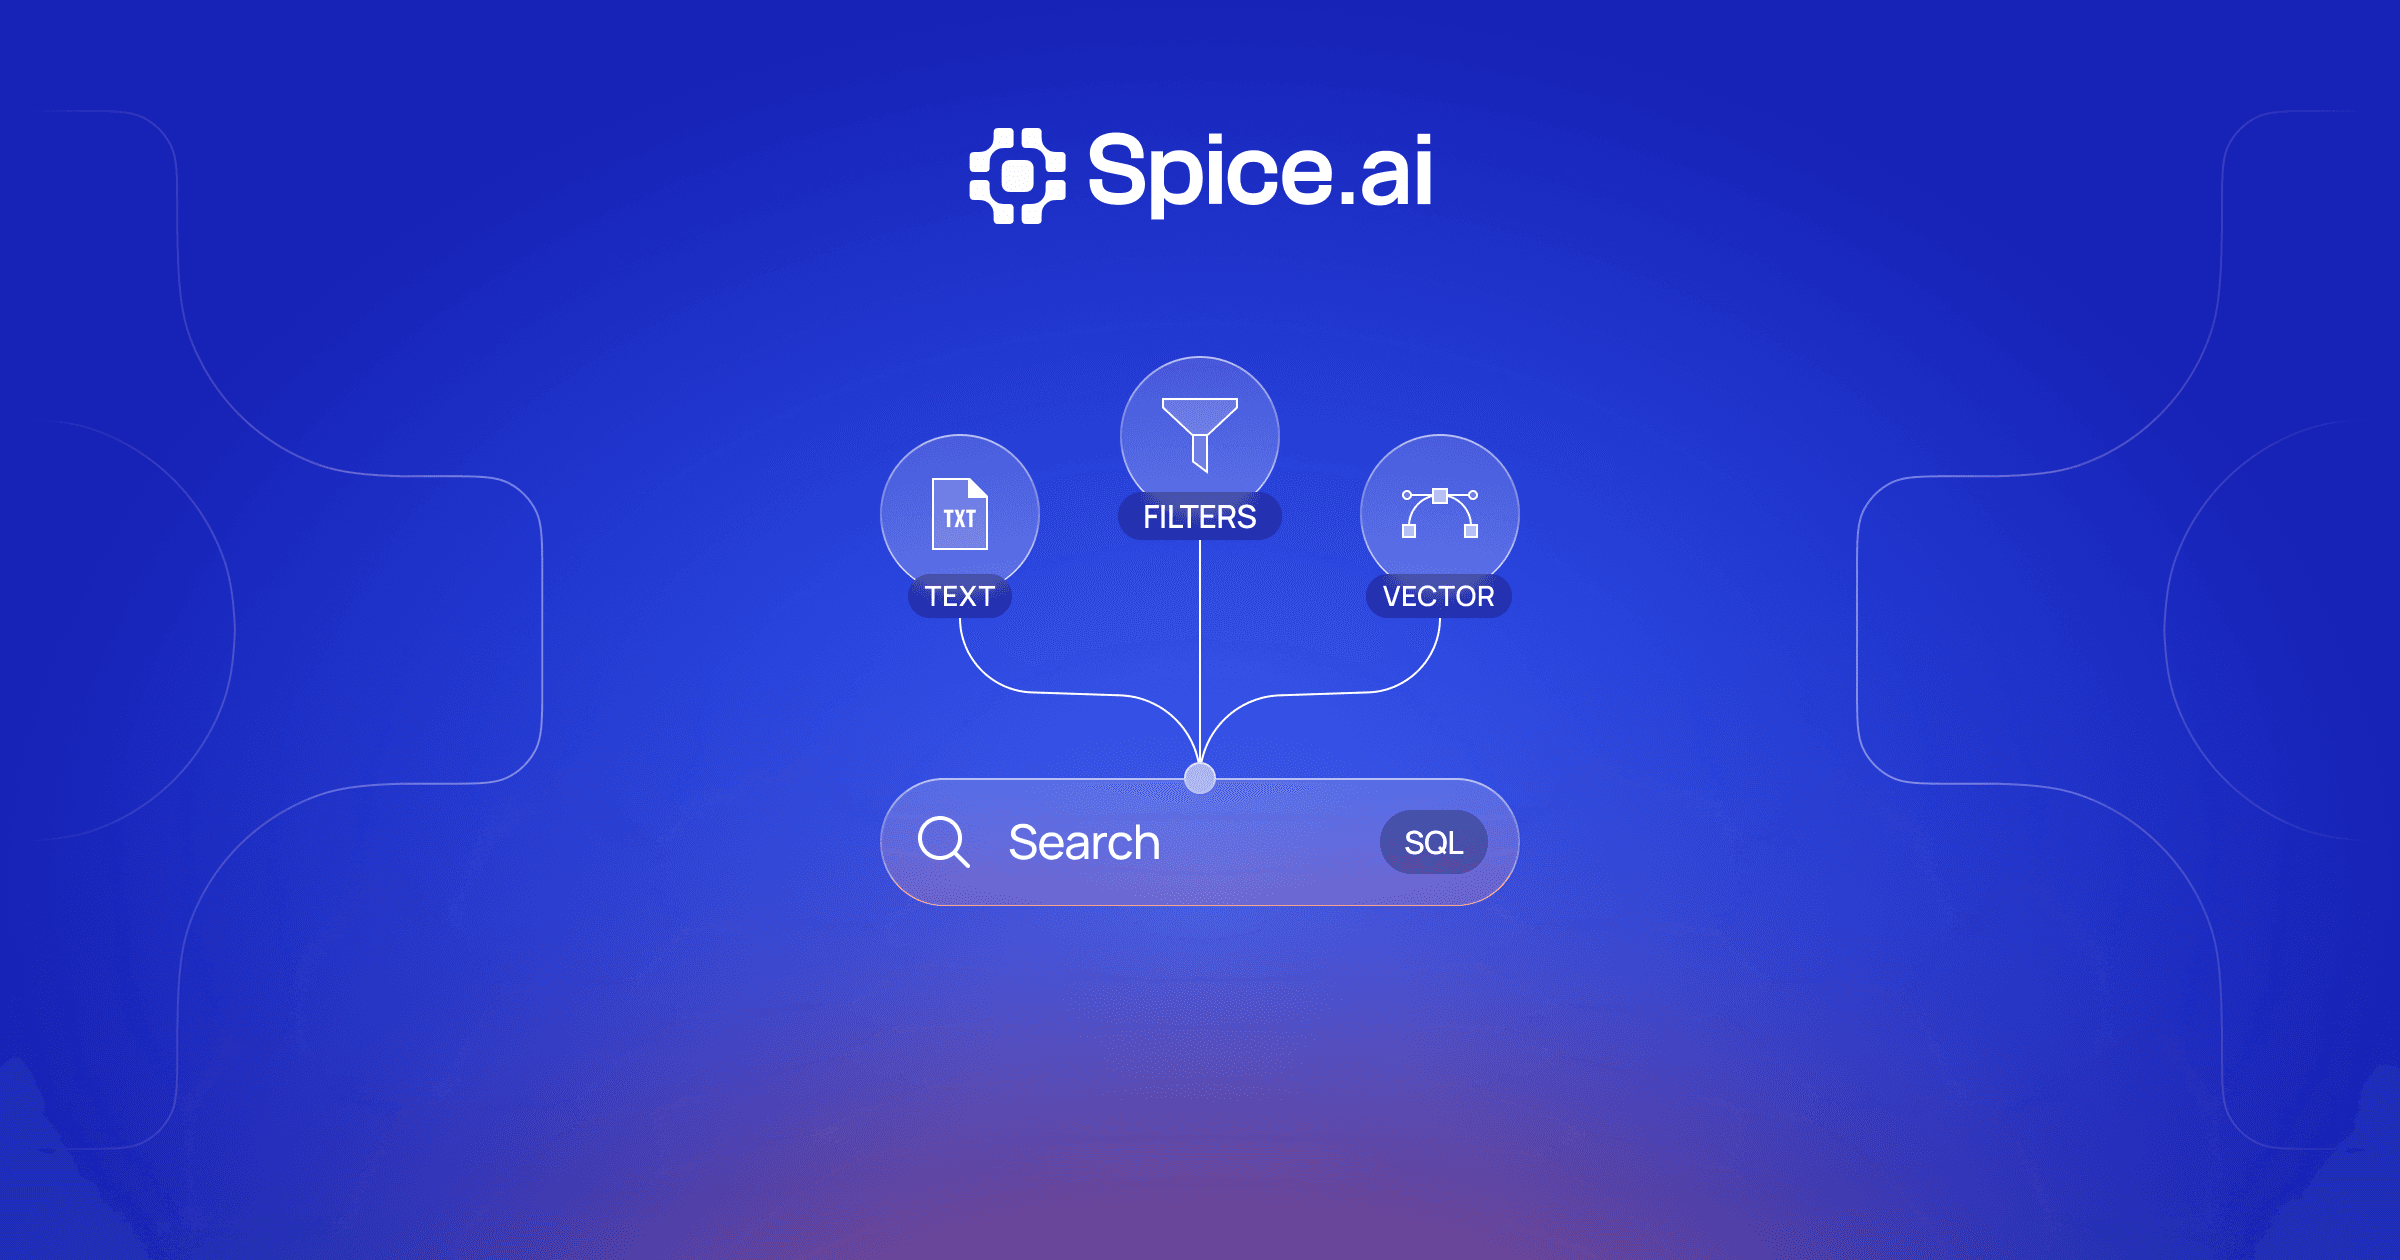
Spice provides robust search capabilities enabling developers to query datasets beyond traditional SQL, including semantic (vector-based) search, full-text keyword search, and hybrid search methods.
True Hybrid Search: Vector, Full-Text, and SQL in One Runtime
TL;DR Show Me the (Data)! It’s well established (and maybe even trite) to say that enterprises are going all-in on artificial intelligence, with more than $40 billion directed toward generative AI projects in recent years. The initial results have been underwhelming. A recent study from the Massachusetts Institute of Technology's NANDA initiative concluded that despite the enormous allocation of […]
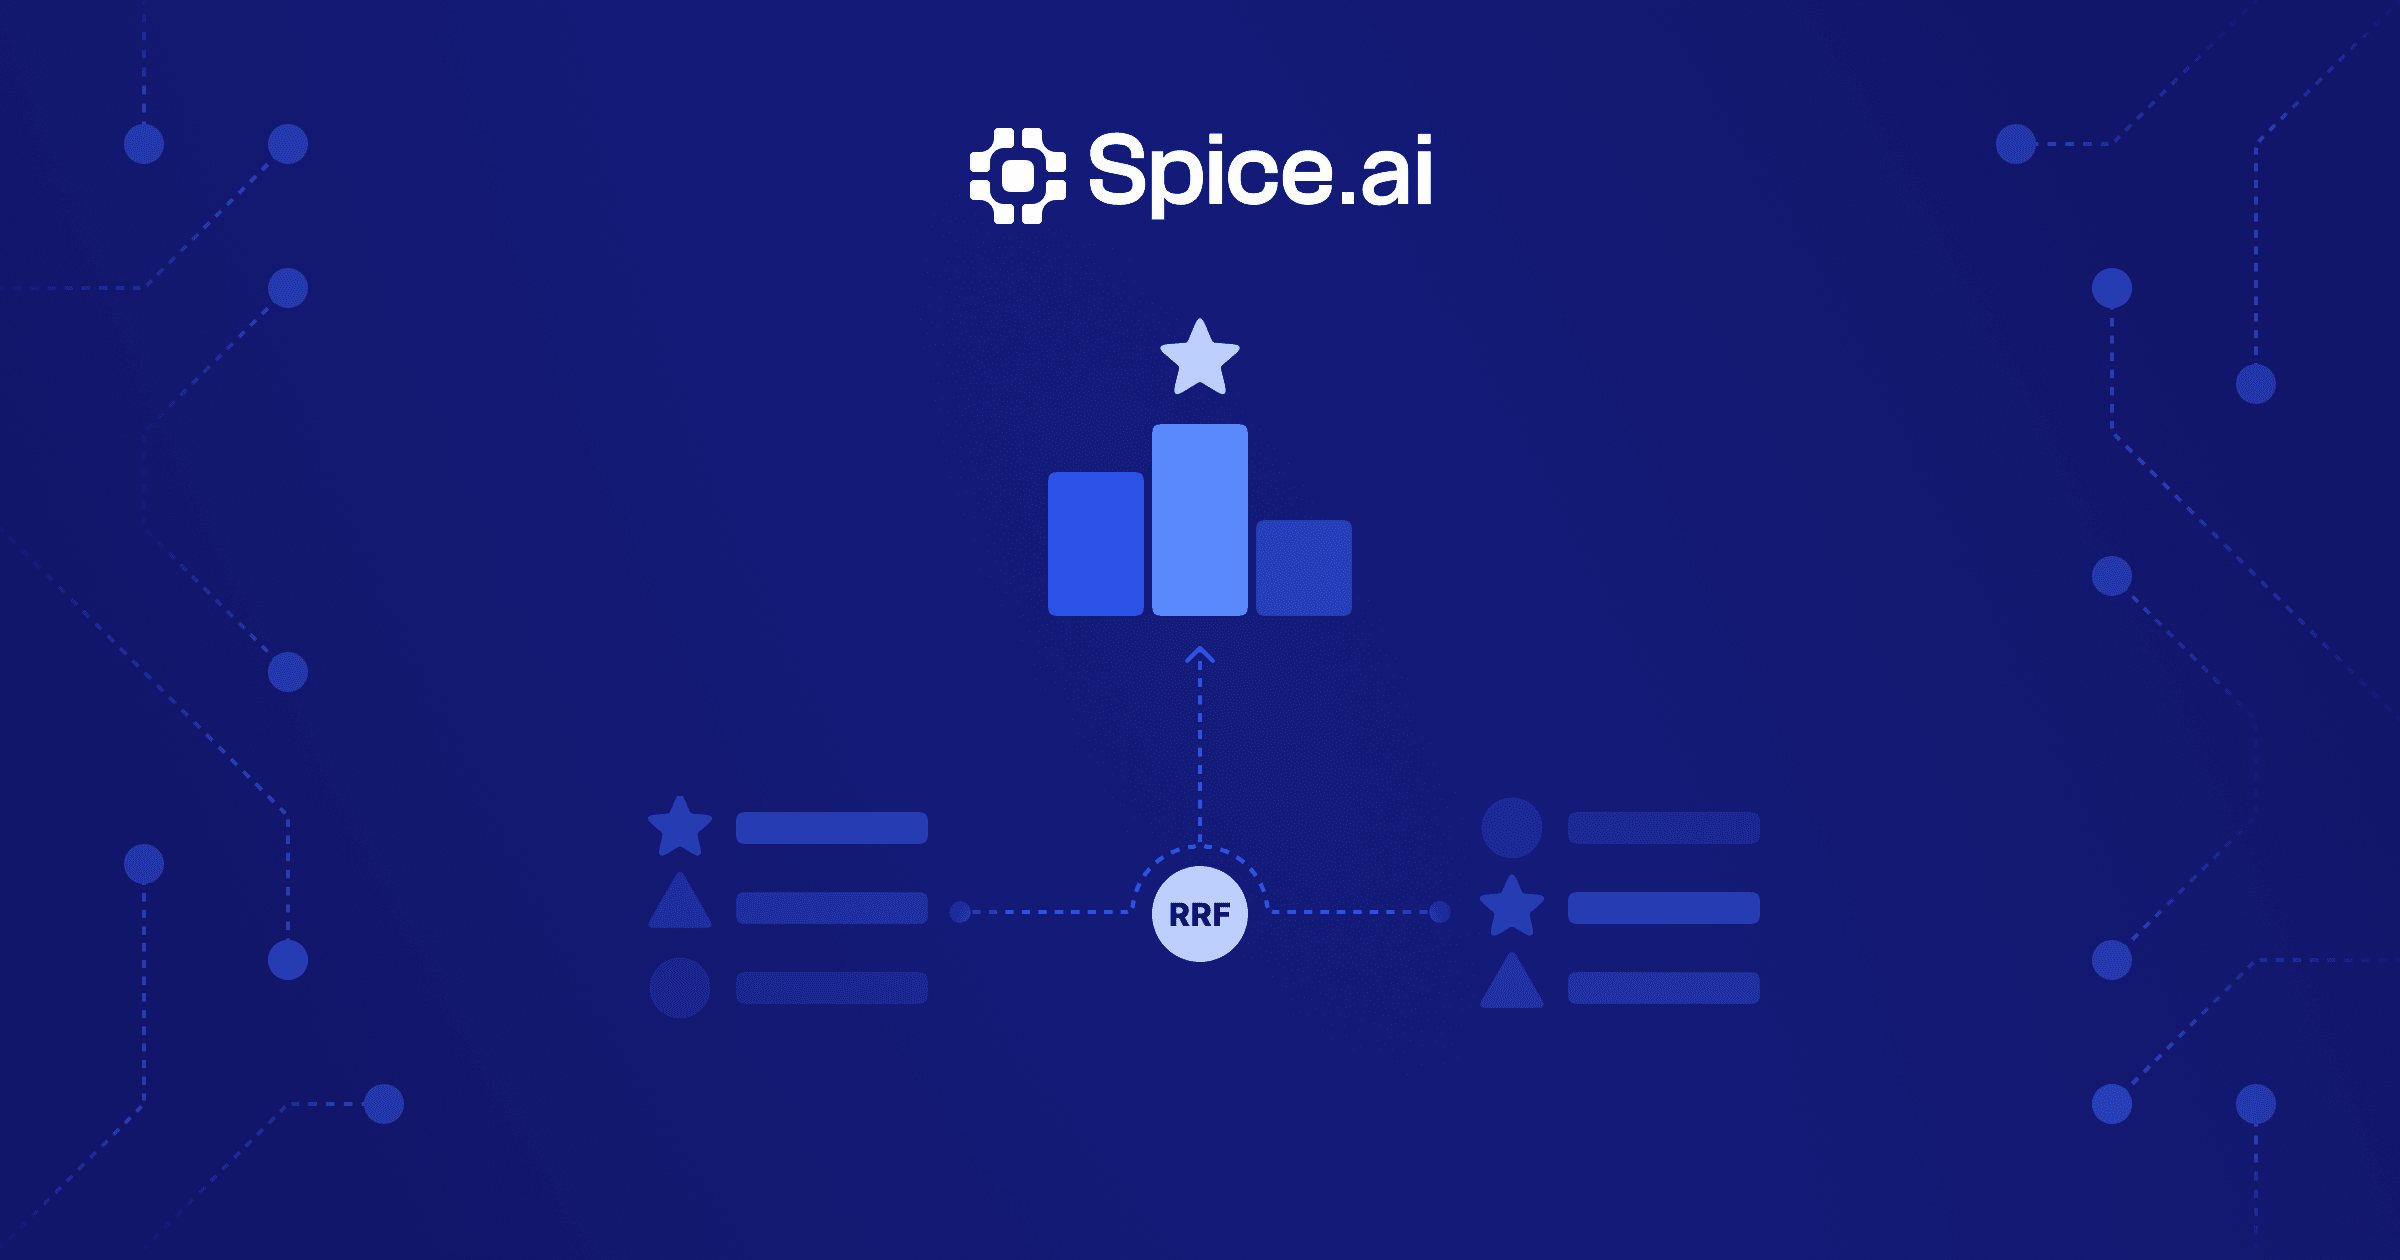
Real-Time Hybrid Search Using RRF: A Hands-On Guide with Spice
Surfacing relevant answers to searches across datasets has historically meant navigating significant tradeoffs. Keyword (or lexical) search is fast, cheap, and commoditized, but limited by the constraints of exact matching. Vector (or semantic) search captures nuance and intent, but can be slower, harder to debug, and expensive to run at scale. Combining both usually entails standing up multiple engines […]
FAQs
Answers to common questions about building RAG pipelines and agentic retrieval with Spice
Agentic retrieval is retrieval that an AI agent directs. The agent decides when to search, which datasets to query, and how to refine a query after it reads the results. In Spice, agents call the built-in search and sql tools through the MCP server gateway or through a model with tools: auto.
RAG reduces hallucinations by grounding model responses in data retrieved at query time instead of relying only on training data. Models grounded in incomplete or outdated data are more likely to hallucinate, so retrieval quality and freshness matter as much as the model itself. Spice retrieves live, governed data with SQL and hybrid search so the context passed to the model stays accurate.
Hybrid search runs vector similarity search and BM25 full-text search in parallel. Reciprocal Rank Fusion (RRF) then merges the two ranked lists into one result. You call it through the /v1/search API or with the vector_search() and text_search() SQL functions. Results are tables, so you can filter, join, and aggregate them like any other dataset.
No. Spice creates embeddings with local or hosted models and runs vector similarity search inside the runtime. A vector database usually needs other systems for text search, keyword search, and joins with structured data. Spice runs all of these in one runtime that you can deploy locally, in your cloud, or as a managed service.
Yes. Spice federates queries across databases, object stores, and APIs with standard SQL. One query can retrieve structured records and combine them with semantic search results. This grounds model responses in operational data without manual data engineering.
Spice invokes models from providers like OpenAI and Anthropic, or local LLMs, through its AI Gateway. Models are called directly in SQL, so retrieved context feeds into generation within the same query workflow. SQL AI functions also classify, label, summarize, and score the sentiment of search results. See LLM inference and AI model serving for how model serving works in Spice.
Spice blends multiple result sets with Reciprocal Rank Fusion (RRF). Each query can set a weight per search, add SQL filters, and boost recent rows. Weight keyword precision for exact lookups, semantic matches for natural-language questions, or recency where freshness matters.
Spice materializes hot data locally with DuckDB, SQLite, or Spice Cayenne acceleration. Large vector indexes can live in Amazon S3 Vectors, which fits millions or billions of embeddings that do not need always-on compute. Index-only reads and filter pushdown keep common queries predictable under high concurrency.
See Spice in action
Walk through your use case with an engineer and see how Spice handles federation, acceleration, and AI integration for production workloads.
Talk to an engineer (opens in a new tab)