The open data
lakehouse for agents

Serve enterprise data to agents securely and at scale on object storage.

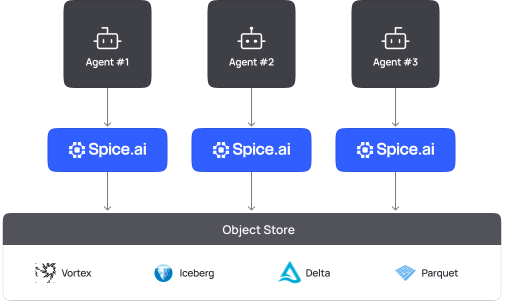
Diagram of three AI agents, each connected through its own Spice.ai instance to a shared object store that holds Vortex, Iceberg, Delta, and Parquet data

Use cases

Spice serves demanding data and AI workloads that need low latency and reliability, and keeps them simple to operate from one deployment to thousands.

Agent data serving

Serve data to agents without per-query costs

Spice gives each agent sandboxed, accelerated access to only the data it needs with search and tools built in. Pay for the compute capacity you provision, measured in vCPU and memory, not for each query your agents run. Costs stay predictable as query volume grows.

Agent data serving

Agent data serving: each agent gets its own Spice instance connected to shared PostgreSQL, Snowflake and S3 sources; query volume grows while capacity stays fixedPostgreSQLSnowflakeS3Agent AAgent BAgent CQuery volume grows, capacity stays fixed.
Query across sources without ETL

Fast queries without ETL delays

Federated SQL across operational databases, warehouses, APIs and more. Accelerate the hot path with fewer pipelines to build and maintain.

Query without ETL

Real-time analytics on operational data

Real-time analytics on operational data

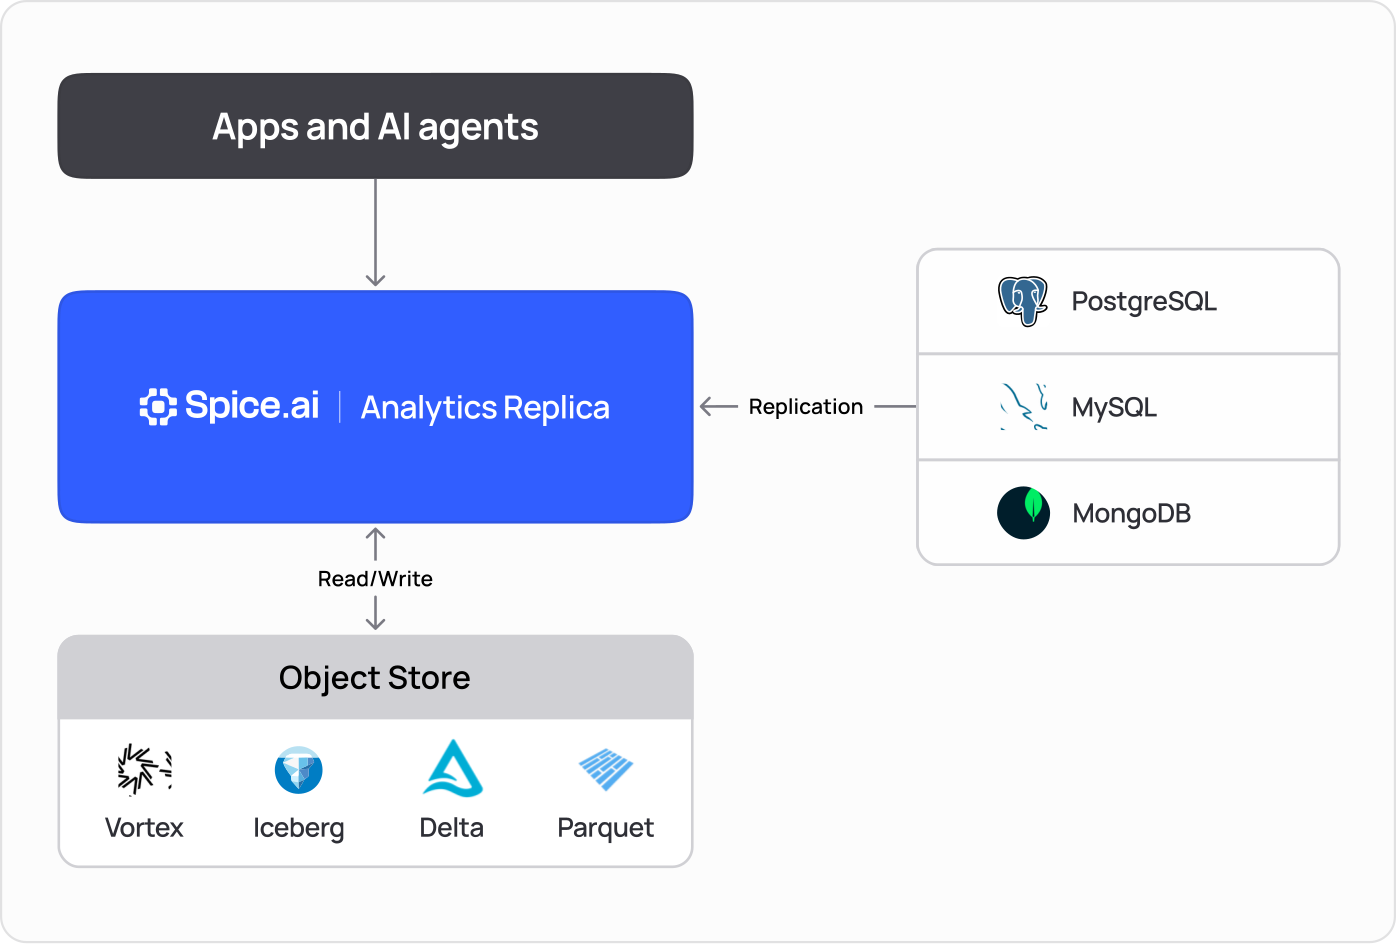
Spice replicates changes from operational databases to an isolated analytics replica via high-throughput CDC, so agents can run large analytical queries against near real-time operational data.

Real-time analytics

Per-tenant agent standardization

One standard lakehouse for every tenant

Spice standardizes lakehouse deployments for every tenant, so adding a customer is a configuration change instead of managing additional data infrastructure. Spice enforces row-level filters and column masking per agent identity, and every agent runs against the same standard configuration.

Per-tenant standardization

Powered by

Proven in production

From messaging platforms to security systems, companies like Twilio and Barracuda rely on Spice to deliver low-latency apps & AI agents at scale.

Peter Janovsky

“Spice opened the door to take these critical control-plane datasets and move them next to our services in the runtime path.”

Peter Janovsky

Software Architect, Twilio

Darin Douglass

100x

Faster queries

“It just spins up and works, which is really nice. The responsiveness is amazing, which is a huge gain for the customer.”

Tim Ottersburg

“Partnering with Spice AI has transformed how NRC Health delivers AI-driven insights. By unifying siloed data across systems, we accelerated AI feature development, reducing time-to-market from months to weeks - and sometimes days. With predictable costs and faster innovation, Spice isn't just solving some of our data and AI challenges - it's helping us redefine personalized healthcare.”

Tim Ottersburg

VP of Technology, NRC Health

Ramachandra Ramarathinam

“Spice is the data plane behind Summation. Every connector we ship, from Snowflake to a generic REST-as-a-table, collapses into one SQL surface, which is what makes our AI agents portable across a customer's stack.”

Ramachandra Ramarathinam

CTO, Summation

Rachel Wong

“Spice AI grounds AI in our actual data, using SQL queries across many data sources. This brings accuracy to probabilistic AI systems, which are very prone to hallucinations.”

Rachel Wong

CTO, Basis Set

Fast, physically isolated access to enterprise data

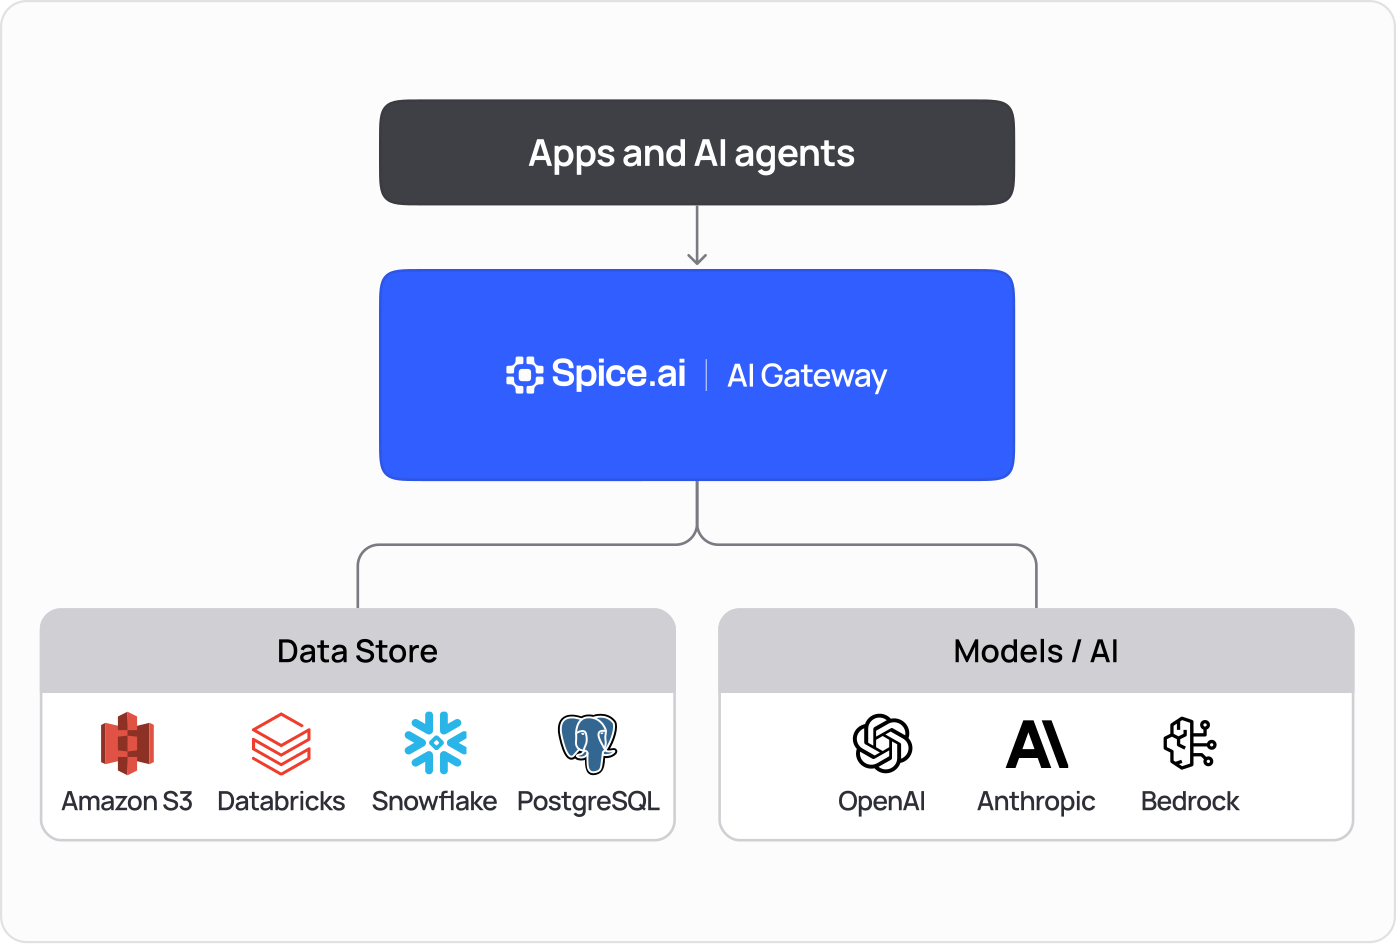
A single SQL endpoint for retrieving, accelerating, searching, and reasoning over operational and analytical data. Incrementally adoptable and built on object storage.

SQL Federation & Acceleration

Fast and federated access to all of your data

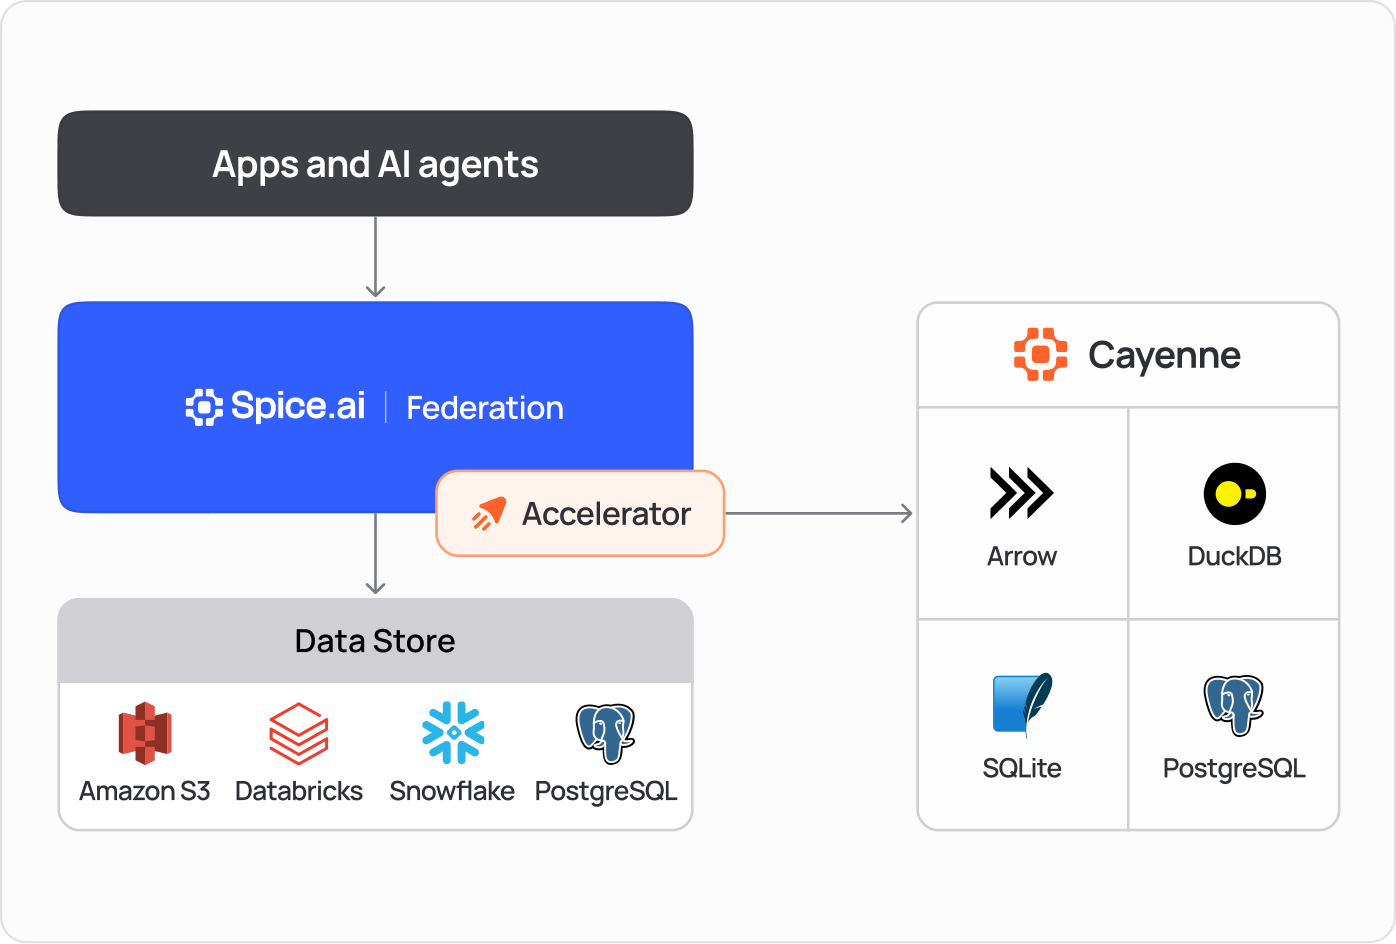
Connect to and query operational databases, data lakes, and warehouses across the enterprise. Materialize and accelerate working sets in-memory or on disk for millisecond access.

SQL federation and acceleration

Spice AI SQL federation and data acceleration architecture
Analytical Query on Operational Data

Real-time analytics without impacting production

Deploy an analytics replica in minutes for fast, isolated queries on real-time operational data.

Analytics on operational data

Spice AI analytics replica architecture overview
Hybrid Search

Combine keyword, vector, and full-text search in SQL

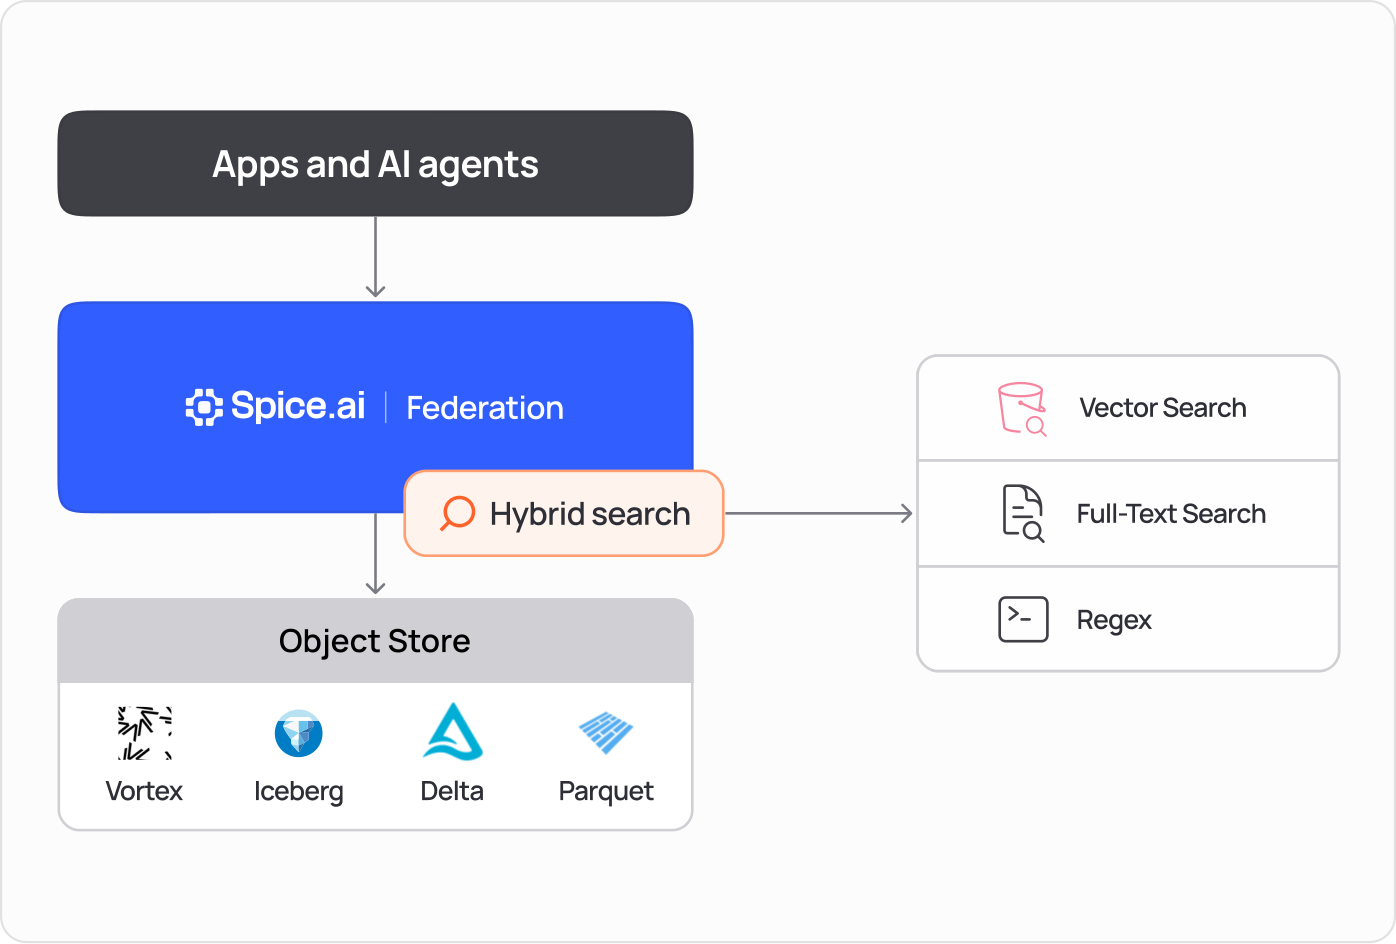
Run hybrid search with standard SQL. Spice combines structured filters, vector similarity, and keyword matches in one query, then ranks the merged results by relevance for search-driven apps.

Hybrid SQL search

Spice AI hybrid SQL search combining keyword, vector, and full-text search
Embedded AI Inference

Call LLMs directly from the query layer

Call hosted or local LLMs inline using SQL UDFs or natural language. Translate text, generate summaries, classify entities, and augment query results on your enterprise data without leaving the Spice runtime.

LLM inference in Spice

Spice AI embedded AI inference with LLM calls from SQL

Serve real-time data to agents

Spice adds high-throughput query and CDC on top of object storage.

  • Query

    31x

    faster than querying object storage directly

  • Ingest

    566K

    rows/s source bootstrap ingest

  • Serve

    266K+

    tpmC of live transactional load, while serving 1,046 analytical queries per hour

  • Query

    1.57x

    faster than DuckDB on the TPC-H SF-100 query set

  • Scale

    300M+

    rows replicated and queried live

  • Scale out

    2.9x

    faster on three nodes than on one

An accelerated lakehouse for every customer, team, and agent

Join Parquet in S3 with a PostgreSQL table in one federated query.

# spicepod.yamldatasets:  - from: s3://spiceai-demo-datasets/taxi_trips/2024/    name: taxi_trips    params: { file_format: parquet, s3_auth: public }  - from: postgres:taxi_zones    name: taxi_zones    params:      pg_host: localhost      pg_port: 15432      pg_db: taxi      pg_user: postgres      pg_pass: ${secrets:SPICE_PG_PASS}      pg_sslmode: disablesql> SELECT z.zone, COUNT(*) AS trips     FROM taxi_trips t                 -- S3     JOIN taxi_zones z                 -- PostgreSQL       ON t."PULocationID" = z.location_id     GROUP BY z.zone ORDER BY trips DESC LIMIT 3;JFK Airport                 145240Midtown Center              143471Upper East Side South       142708Time: 2.705 seconds

One spicepod.yaml file defines the lakehouse: SQL federation across your data sources, plus acceleration, search, and inference. The Spice Cloud API deploys it for each customer, internal team, or agent.

Every deployment runs the same standard lakehouse, so operating hundreds stays simple. Each can still use its own data sources and settings. A SaaS company can give each customer its own lakehouse; an enterprise data platform team can do the same for each internal team.

A coding agent can write and run the spicepod for you in minutes.

  1. /plugin marketplace add spiceai/skills
  2. /plugin install spiceai@spiceai

Control and optionality at every layer

Run real-time apps and AI agents on existing data, with control over where Spice runs, what each agent can read, and how every request performs.

Edge-to-cloud

Run Spice.ai Open Source locally, at the edge, or on the fully managed Spice.ai Cloud Platform. Lightweight, portable, and designed for scale.

Deploy anywhere

AI sandboxing
& security

Provision isolated, least-privilege datasets for apps and agents with zero direct database access. Keep governance intact while enabling RAG, agents, and AI workflows.

Secure AI sandboxing

Distributed
observability

Perform end-to-end tracing across SQL, embeddings, search, and LLM calls. Debug, measure latency, and prove ROI from a single view.

Observability docs (opens in a new tab)

How Spice scales

Your data lives in object storage. Spice serves that data to agents from three tiers so recent data is returned fastest and higher volumes of data stay cheap.

Tiered storage

Data tiered by latency and freshness demands

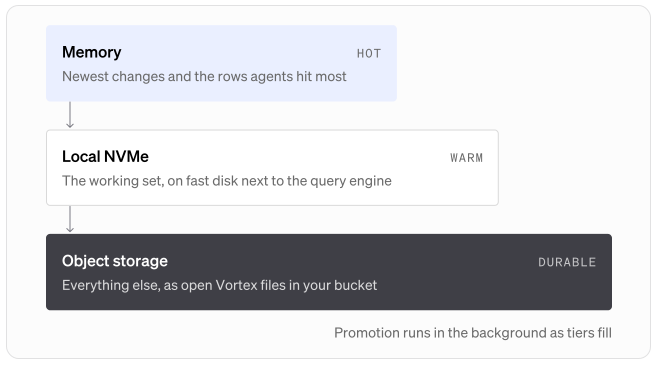
New and frequently read rows live in memory, and the warm working set lives on local NVMe next to compute. Older data moves to object storage as Vortex files, in the background, as each tier fills.

View the docs (opens in a new tab)

Three storage tiers. Memory holds the newest changes and the rows agents hit most. Local NVMe holds the working set next to the query engine. Object storage holds everything else as open Vortex files. Promotion runs in the background as tiers fill.
Scale out

Scale from one node to a cluster

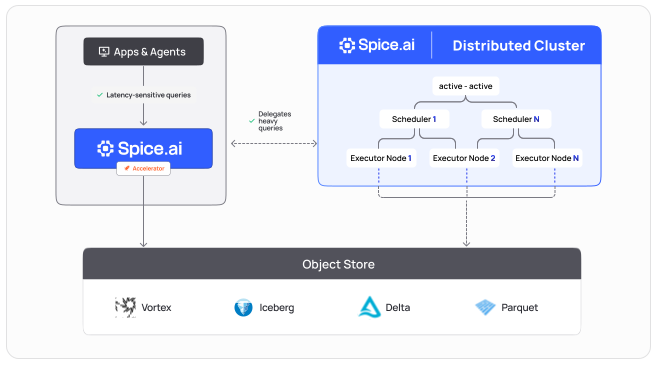
Spice runs as a single node, as a microservice, or as a multi-node cluster. The cluster-sidecar topology deploys a Spice sidecar next to each app or AI agent, backed by a multi-node cluster.

Each sidecar materializes only the working set its app or agent needs, and serves and caches it locally. When a query needs data beyond that working set, the sidecar delegates to the cluster.

View the docs (opens in a new tab)

Apps and agents send latency-sensitive queries to a Spice sidecar with a local accelerator. The sidecar delegates heavy queries to a Spice distributed cluster, where active-active schedulers assign work to executor nodes. The sidecar and the executor nodes read Vortex, Iceberg, Delta, and Parquet files from the object store.

Watch Spice in action

Demos from the founders and engineers who built it.

FAQs

Common questions about what Spice AI is, how it works, and how teams run it.

Spice AI builds Spice, an open-source engine for SQL query, search, and LLM inference over enterprise data. Applications and AI agents use one SQL endpoint to query databases, data lakes, and warehouses. Spice can also keep an analytics replica of an operational database, so analytical reads do not load production. Teams run Spice on their own infrastructure or use the managed Spice Cloud Platform.

Spice is written in Rust and uses Apache DataFusion as its SQL query engine. Data moves through the runtime in the Apache Arrow columnar format. Apache Ballista runs distributed queries across a cluster. The Spice Cayenne accelerator stores local copies in the Vortex columnar format.

No. Spice runs next to existing databases, data lakes, and warehouses, and those systems stay the source of truth. Applications keep writing to the operational database. Spice serves reads through SQL federation and acceleration, from the source or from a local accelerated copy. Teams can add Spice one dataset at a time, without a data migration.

AI agents query Spice through three interfaces: a SQL API, an OpenAI-compatible chat API, and an MCP server. The SQL API runs queries that the agent writes. The chat API lets a model call built-in SQL and search tools. The MCP server connects agent frameworks that use the Model Context Protocol.

Spice runs on a laptop, on-premises, at the edge, or in any cloud. Teams deploy it as a sidecar next to an application, as a shared microservice, or as a distributed cluster on Kubernetes. The Spice Cloud Platform runs Spice as a managed service. See edge-to-cloud deployments for each option.

Yes. Spice.ai Open Source is free under the Apache 2.0 license, with community support on GitHub and Slack. Spice Cloud adds a managed service with subscription and usage-based plans. Enterprise plans add commercial licensing, 24/7 support, and SLAs. See pricing to compare the plans.

Twilio, Barracuda Networks, NRC Health, Basis Set, and Summation run Spice in production. The Spice 1.0 announcement from January 2025 reports P99 query times under 5 milliseconds for the Twilio messaging control plane. The Barracuda case study, published in June 2026, reports data lake query responses up to 100x faster.

See Spice in action

Walk through your use case with an engineer and see how Spice handles federation, acceleration, and AI integration for production workloads.

Talk to an engineer (opens in a new tab)