date: 2026-01-22 title: 'Spice v1.11.0-rc.2 (Jan 22, 2026)' type: blog authors: [krinart] tags: [release, cayenne, acceleration, datafusion, iceberg, snapshots, scylladb, data-connector, distributed-query, caching, dynamodb]
Announcing the release of Spice v1.11.0-rc.2! :star:
v1.11.0-rc.2 is the second release candidate for advanced test of v1.11. It brings Spice Cayenne to Beta status with acceleration snapshots support, a new ScyllaDB Data Connector, upgrades to DataFusion v51, Arrow 57.2, and iceberg-rust v0.8.0. It includes significant improvements to distributed query, caching, and observability.
Spice Cayenne (opens in a new tab) has been promoted to Beta status with acceleration snapshots support and numerous stability improvements.
Improved Reliability:
FuturesUnordered reentrant drop crashescayenne_file_path locationExample configuration with snapshots:
Apache DataFusion has been upgraded to v51 (opens in a new tab), bringing significant performance improvements, new SQL features, and enhanced observability.
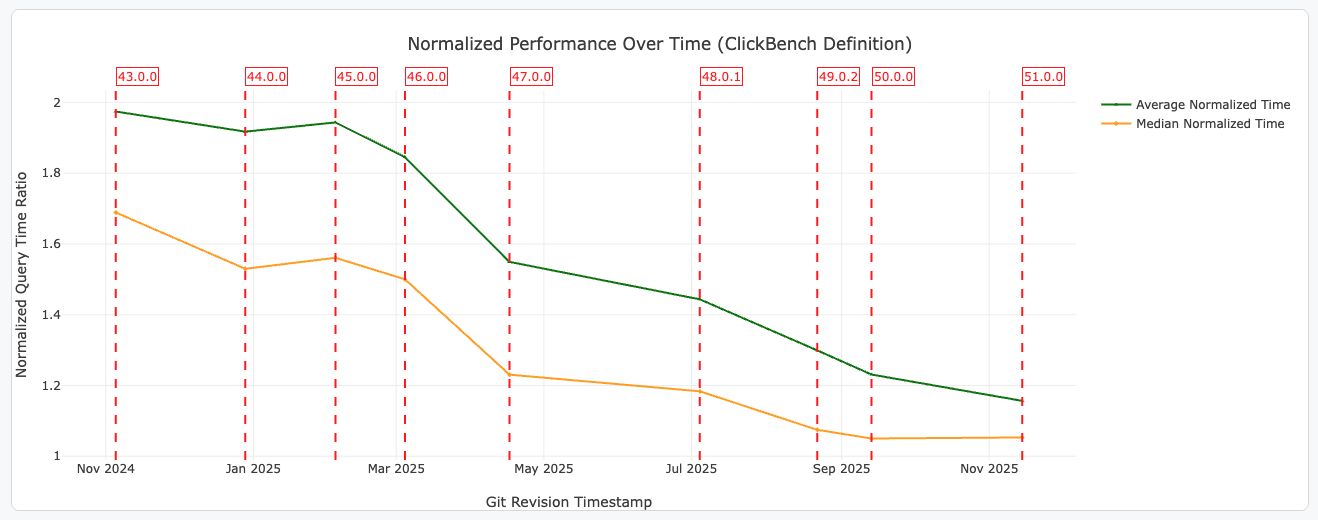
Performance Improvements:
CASE Expression Evaluation: Expressions now short-circuit earlier, reuse partial results, and avoid unnecessary scattering, speeding up common ETL patternsNew SQL Features:
|> syntax for inline transformsDESCRIBE <query>: Returns the schema of any query without executing itparam => value syntax for scalar, aggregate, and window functionsSUM, AVG, and MIN/MAXExample pipe operator:
Improved Observability:
EXPLAIN ANALYZE Metrics: New metrics including output_bytes, selectivity for filters, reduction_factor for aggregates, and detailed timing breakdownsSpice has been upgraded to Apache Arrow Rust 57.2.0 (opens in a new tab), bringing major performance improvements and new capabilities.
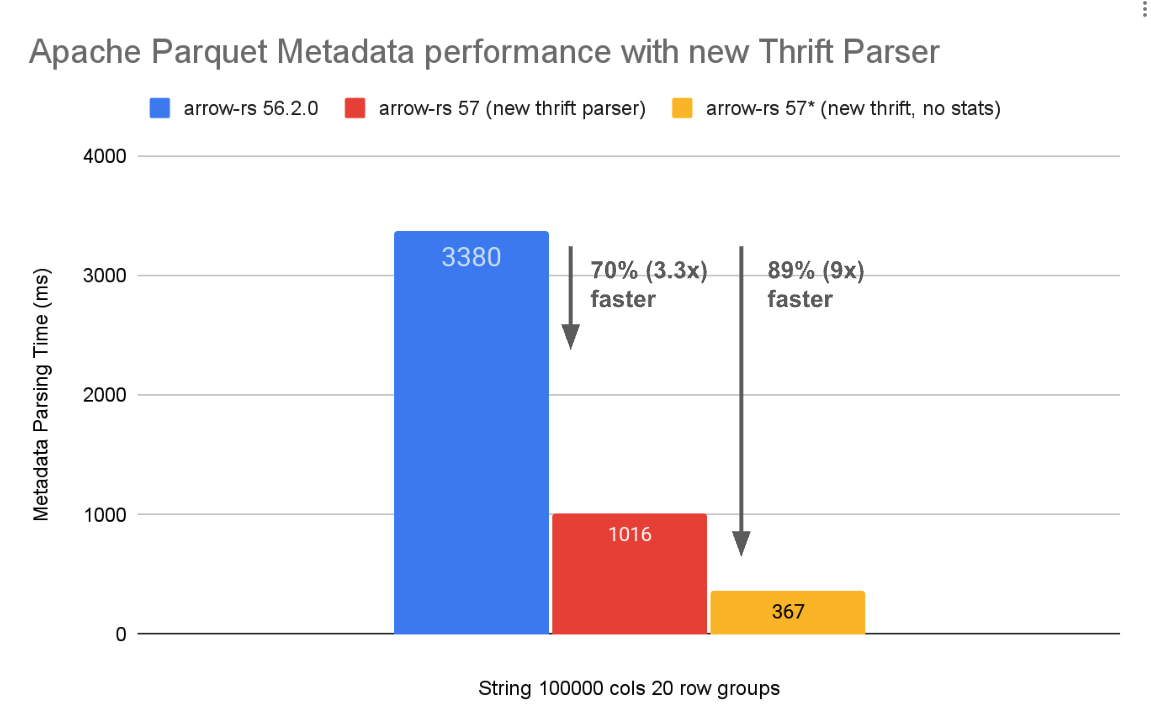
Key Features:
GEOMETRY and GEOGRAPHY) with GeospatialStatisticsarrow-avro Crate: Efficient conversion between Apache Avro and Arrow RecordBatches with projection pushdown and vectorized execution supportSpice has been upgraded to iceberg-rust v0.8.0 (opens in a new tab), bringing improved Iceberg table support.
Key Features:
INSERT INTO Partitioned Tables: DataFusion integration now supports inserting data into partitioned Iceberg tablesupdate_table and register_table for SQL catalogupdate_table for S3 Tables catalog_file column support, and Date32 type supportAcceleration snapshots enable point-in-time recovery and data versioning for accelerated datasets. Snapshots capture the state of accelerated data at specific points, allowing for fast bootstrap recovery and rollback capabilities.
Key Feature Improvements in v1.11:
Example configuration:
Snapshots API and CLI: New API endpoints and CLI commands for managing snapshots programmatically. List, create, and restore snapshots directly from the command line or via HTTP.
For more details, refer to the Acceleration Snapshots Documentation (opens in a new tab).
A new data connector for ScyllaDB (opens in a new tab), the high-performance NoSQL database compatible with Apache Cassandra. Query ScyllaDB tables directly or accelerate them for faster analytics.
Example configuration:
For more details, refer to the ScyllaDB Data Connector Documentation (opens in a new tab).
mTLS Verification: Cluster communication between scheduler and executors now supports mutual TLS verification for enhanced security.
Credential Propagation: Azure and GCS credentials are now automatically propagated to executors in cluster mode, enabling access to cloud storage across the distributed query cluster.
Improved Resilience:
--scheduler-address is providedFor more details, refer to the Distributed Query Documentation (opens in a new tab).
The Caching Acceleration Mode (opens in a new tab) introduced in v1.10.0 has received significant performance optimizations and reliability fixes in this release.
Performance Optimizations:
Reliability Fixes:
fetched_at in their projection would always result in cache misses, even when cached data was available.SELECT * queries without filters now return cached data directly without unnecessary filtering overhead.For more details, refer to the Caching Acceleration Mode Documentation (opens in a new tab).
Query data sources directly via URL in SQL without prior dataset registration. Supports S3, Azure Blob Storage, and HTTP/HTTPS URLs with automatic format detection and partition inference.
Supported Patterns:
SELECT * FROM 's3://bucket/data.parquet'SELECT * FROM 's3://bucket/data/'SELECT * FROM 's3://bucket/year=*/month=*/data.parquet'Key Features:
Example with hive partitioning:
Enable via spicepod.yml:
New asynchronous query APIs for long-running queries in cluster mode:
/v1/queries endpoint: Submit queries and retrieve results asynchronouslyEnhanced Dashboards: Updated Grafana and Datadog example dashboards with:
Additional Histogram Buckets: Added more buckets to histogram metrics for better latency distribution visibility.
For more details, refer to the Monitoring Documentation (opens in a new tab).
on_refresh_sort_columns parameter for DuckDB enables data ordering after writesNo breaking changes.
New ScyllaDB Data Connector Recipe: New recipe demonstrating how to use ScyllaDB Data Connector. See ScyllaDB Data Connector Recipe (opens in a new tab) for details.
New SMB Data Connector Recipe: New recipe demonstrating how to use ScyllaDB Data Connector. See SMB Data Connector Recipe (opens in a new tab) for details.
The Spice Cookbook (opens in a new tab) includes 86 recipes to help you get started with Spice quickly and easily.
To upgrade to v1.11.0-rc.2, use one of the following methods:
CLI:
Homebrew:
Docker:
Pull the spiceai/spiceai:v1.11.0-rc.2 image:
For available tags, see DockerHub (opens in a new tab).
Helm:
AWS Marketplace:
Spice is available in the AWS Marketplace (opens in a new tab).
table_allowlist for table sampling and NSQL by @Jeadie (opens in a new tab) in #8789 (opens in a new tab)auth/iam_role_source to DynamoDB connector by @krinart (opens in a new tab) in #8808 (opens in a new tab)UnionProjectionPushdownOptimizer - Schema change during transform_down breaks parent nodes by @phillipleblanc (opens in a new tab) in #8831 (opens in a new tab)release/1.11 branch by @ewgenius (opens in a new tab) in #8829 (opens in a new tab)testoperator run text-to-sql metrics from LogicalPlan by @Jeadie (opens in a new tab) in #8895 (opens in a new tab)BootstrapStatus + Snapshot bootstrapping parallelization by @krinart (opens in a new tab) in #8926 (opens in a new tab)cayenne_metadata_dir to known params by @sgrebnov (opens in a new tab) in #8933 (opens in a new tab)snapshots_creation_policy param by @krinart (opens in a new tab) in #8954 (opens in a new tab)data_components arrow::indexed::test_primary_key_value_matches_batch by @Jeadie (opens in a new tab) in #8962 (opens in a new tab)testoperator run text-to-sql. by @Jeadie (opens in a new tab) in #8927 (opens in a new tab)Chat::as_sql for xAI anthropic by @Jeadie (opens in a new tab) in #8957 (opens in a new tab)duckdb_file_path in search integration test by @Jeadie (opens in a new tab) in #8972 (opens in a new tab)on_refresh_sort_columns for post-write data ordering (initial version) by @sgrebnov (opens in a new tab) in #8964 (opens in a new tab).spice/data in search integration tests by @Jeadie (opens in a new tab) in #8992 (opens in a new tab)snapshots_creation_policy by @krinart (opens in a new tab) in #9003 (opens in a new tab)